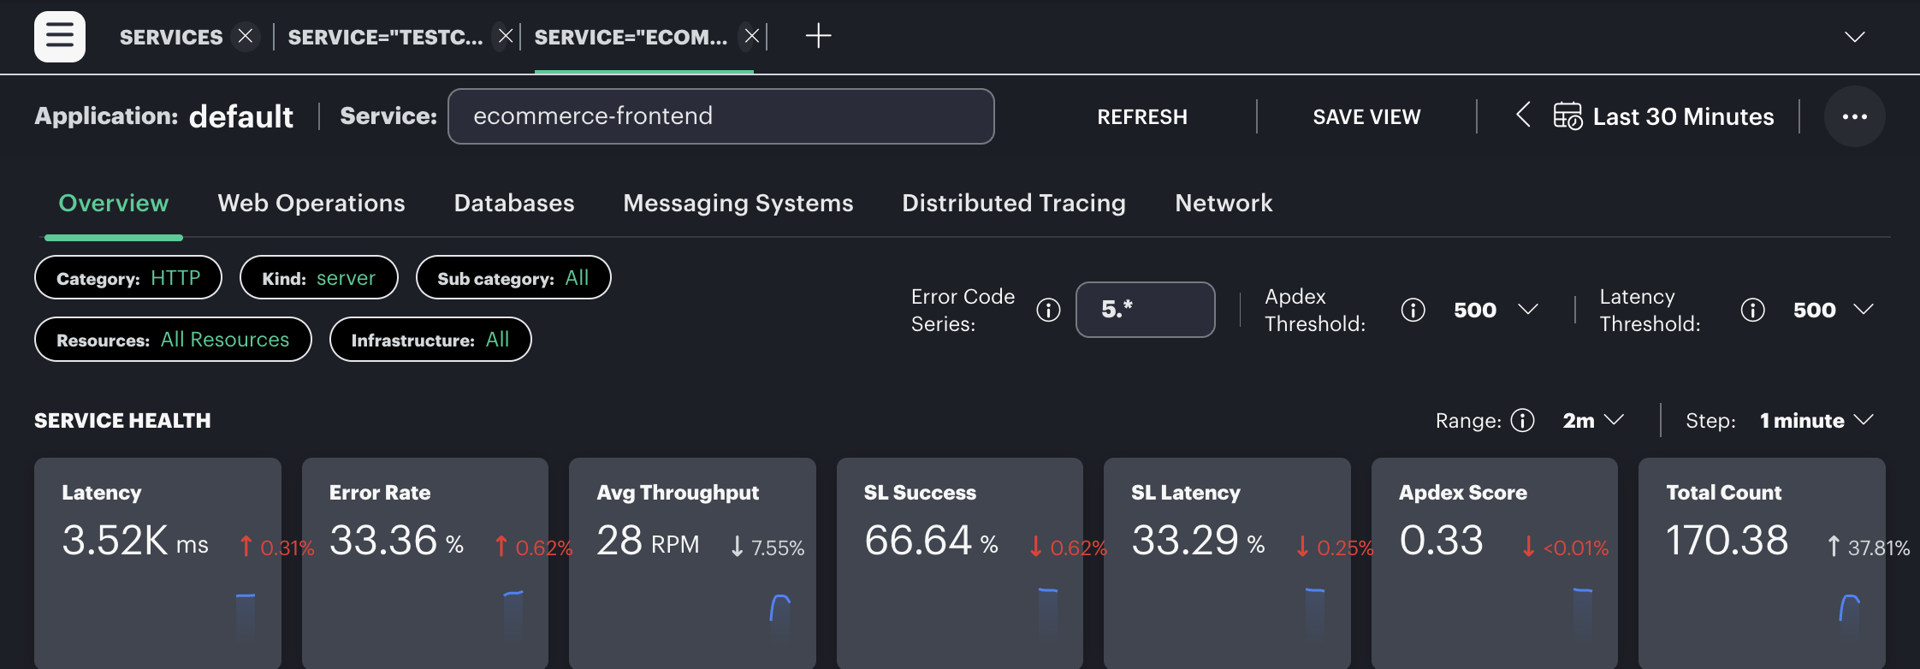
Use trace-derived service metrics to detect changes in latency, errors, and throughput. Alerts turn metric conditions into notifications; service objectives provide the operating target and evaluation window used to choose meaningful conditions.
Plan before creating alerts
Define the affected service or operation, metric, evaluation window, threshold, severity, and recovery condition. Compare the proposed threshold with normal traffic at several times of day. A useful alert identifies customer impact and has a clear owner and response action.
Availability of alert-definition fields, notification policies, service-level objective views, and analytics features depends on enabled OpsRamp capabilities and permissions. The trace pages supply service metrics; use the alerting and dashboard features available in your deployment to operationalize them.